Open Source · Apache 2.0 100% Managed Vertex AI · Zero GKE

Bring Your Own Open Weights. Tune & Serve Serverlessly on Vertex AI Model Garden.

Import Hugging Face .safetensors checkpoints (Qwen 3, Llama 3.1/3.3, Gemma 3, Mistral, DeepSeek) directly from Cloud Storage to Managed Vertex AI Dedicated Endpoints (vLLM / SGLang), fine-tune custom weights with overridden hyperparameters via Global Serverless Open Model Tuning, and evaluate accuracy via the OpenAI SDK. Zero GKE clusters to operate, zero vendor lock-in, and one-command Google Cloud Shell automation.

~9m
Managed vLLM Deploy Time
4 Stages
Automated Cloud Shell Pipeline
100%
Portable .safetensors Export
Zero GKE Overhead · Managed Dedicated Endpoint
vertex-ai · global-sft + vllm
LIVE
TUNING TOKEN COST
~$0.09
~64K tok · $0 queue/idle
UNTUNED BASELINE
0 / 8
0.0% schema match · 17.5s
MEASURED LATENCY · g4-standard-48 17.50s → 3.28s (−81.3%)
list_deploy_options(available_machines=True) -> g4-standard-48
Global GPU Routing · Avoids code: 8
Vertex AI Model Garden CustomModel SDK Qwen/Qwen3-4B Managed vLLM & SGLang google-genai Global Tuning OpenAI Chat Completions Hugging Face .safetensors Google Cloud Storage Google Cloud Shell 100% Offline CI Suite
NEW · v1.0.0 Global Serverless Open Model Tuning (location="global" via google-genai) + One-Command Cloud Shell Runner (./deploy/run_cloud_shell.sh) with automatic lazy service-agent IAM retry.
Release Notes →
INTERACTIVE COMMAND CONSOLE

Inspect Every Layer Before Provisioning GPUs

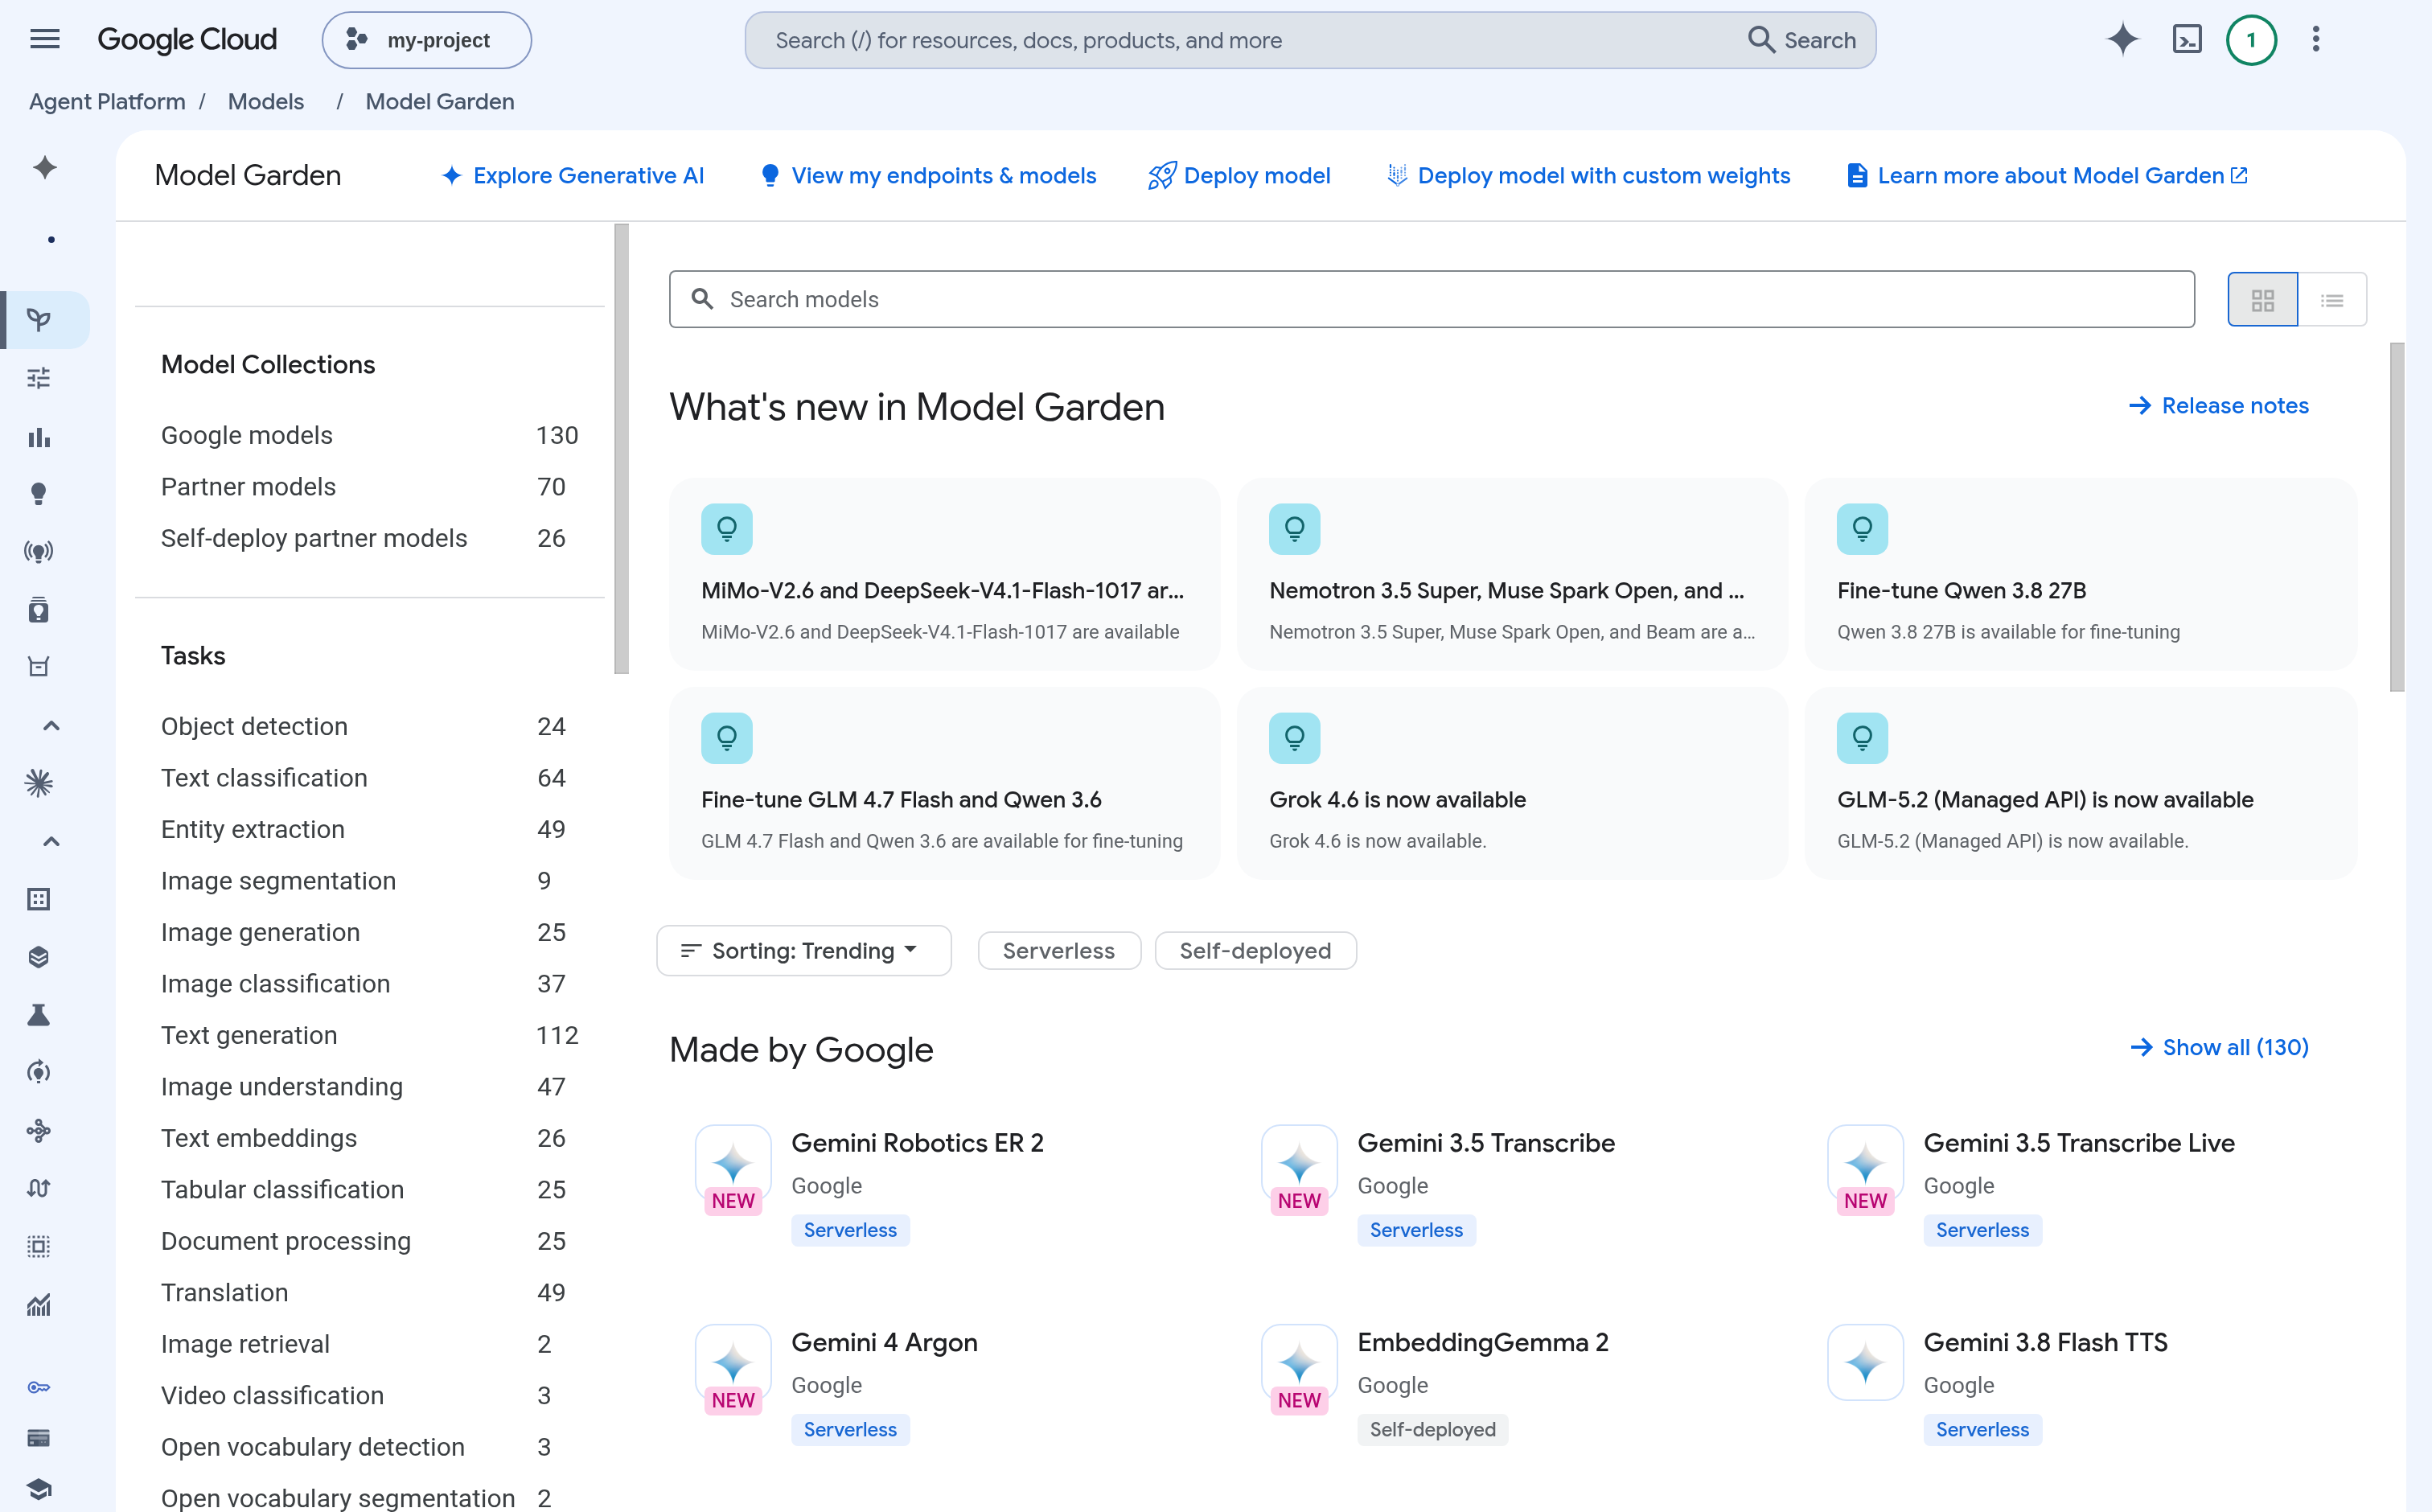
Browse 8 real Google Cloud Console screenshots, inspect Cymbal enterprise incident triage telemetry, copy verified Python SDK & OpenAI snippets, and audit least-privilege IAM bindings.

8 Verified Console Captures · Click Image to Zoom
←→ step through captures Real Google Cloud Console UI
console.cloud.google.com/vertex-ai/model-garden
ARCHITECTURE & CAPABILITIES

Managed Open-Weight Infrastructure, Zero Kubernetes Tax

Every stage runs on serverless or managed tenant infrastructure—giving you full Hugging Face weight portability without operating GPU node pools.

FLAGSHIP LOOP · ZERO GKE vLLM + Global SFT

End-to-End BYOM Loop — Hugging Face .safetensors → Global Serverless Tuning → Managed vLLM Endpoint

Stage any supported open-weight checkpoint (Qwen 3, Llama 3.1/3.3, Gemma 3, Mistral, DeepSeek) to Cloud Storage, benchmark out-of-the-box accuracy, run full-parameter or LoRA serverless SFT with custom hyperparameters, and re-deploy the exported .safetensors checkpoint to an isolated Dedicated Endpoint.

gs://<BUCKET>/hf-weights/Qwen--Qwen3-4B ──► CustomModel.deploy() ──► tunings.tune(location="global")
01 · INGEST
HF .safetensors
11 files · 8.06 GB staged
02 · SERVE AS-IS
Managed vLLM
~9m Dedicated Endpoint
03 · CUSTOMIZE
Global SFT
FULL · epochs=5 · lr=5e-5
04 · EXPORT
Open Weights
checkpoints/final/*.safetensors
AUTO HARDWARE DISCOVERY

Live GPU Stock & Quota Auto-Selection

Eliminates blind SKU guessing and 40-minute stockout stalls by querying live regional accelerator availability filtered strictly by your project's active serving quota.

custom_model.list_deploy_options(available_machines=True, filter_by_user_quota=True)
AVOIDS CODE: 8

Global Capacity Routing

Routes serverless SFT across supported multi-GPU regions automatically via google-genai.

genai.Client(location="global")
CUSTOM SFT

Non-Default Hyperparameter Control

Override Model Garden defaults (3 epochs, 7.5e-5) with custom schedules across FULL and PEFT_ADAPTER modes.

epoch_count=5, learning_rate=5e-5
DROP-IN SDK COMPATIBILITY

Dual OpenAI + Native endpoint.predict() Serving

Query Managed Dedicated Endpoints (*.prediction.vertexai.goog) simultaneously via the standard OpenAI Chat Completions Python client and Vertex AI's native prediction SDK.

POST /v1beta1/.../endpoints/{ID}/chat/completions + endpoint.predict(use_dedicated_endpoint=True)
100% OPEN WEIGHTS

Zero Lock-In .safetensors Checkpoint Export

Serverless Open Model Tuning writes unencrypted Hugging Face .safetensors shards, config.json, and tokenizer files directly to your Cloud Storage bucket—ready for Vertex AI, on-prem vLLM, or local workstations.

gs://<BUCKET>/tuning-runs/.../postprocess/node-0/checkpoints/final
ZERO CLOUD SECRETS

100% Offline CI & Dry-Run Suite

Verify CLI flags, dataset byte ratios (<=25%), asset parity, and --emit-iam output completely offline.

unittest discover -s tests -v
ESTIMATED COST & TIMING

What Running This Tutorial Costs & Takes

Serverless Tuning is billed strictly per 1M training tokens ($0 for queue or export wait), while Dedicated GPU Endpoints bill only while deployed.

Illustrative Estimation Only — Not Official Pricing: Ballpark estimates based on public us-central1 reference rates to give you a rough idea before running. Always check official Vertex AI Generative AI Pricing, Vertex AI Pricing, and Cloud Storage Pricing.
Estimated Tutorial Total
~$0.60 – $2.20
End-to-end 4-stage run with --auto-cleanup
Serverless Fine-Tuning
~$0.09
Qwen 3 4B · 120 rows × 5 epochs (~64K tok) · $0 queue/idle fee
Expected Wait Time
~1 – 3.5 hrs
41m 15s measured via location="global" + ~24m deploy & eval
Stage / Resource How Vertex AI Bills It This Tutorial (120 rows, --auto-cleanup) Larger Example (10K rows × 500 tok × 3 epochs)
Serverless Open Model Tuning Qwen 3 4B ~$1.35 / 1M training tokens ($0 queue/export) ~$0.09 ~64K billable tokens ~$20.25 15M tokens
Dedicated GPU Endpoint Serving Per active replica-hour (L4 ~$1.15/hr · RTX PRO 6000 ~$5.18/hr) ~$0.50 – $2.10 2 × ~12m deploy + eval cycles; base GPU deleted during tuning Scales per active hour or $0 idle with Scale-to-Zero
Cloud Storage gs://... ~$0.020 / GB-month (~16 GB base + tuned .safetensors) ~$0.01 / day ~$0.32 / month ~$0.32 / month
Wall-Clock Wait Time Unattended in Cloud Shell ~40m – 3.5h tuning + ~24m deploy/eval ~2 – 5h depends on token volume & global GPU queue
Built-in Cost Guardrail: ./deploy/run_cloud_shell.sh deletes the temporary base GPU endpoint before fine-tuning starts (avoiding ~$13 in idle GPU charges while tuning runs) and supports --auto-cleanup.

Bucket-Scoped IAM

Grants roles/storage.objectUser strictly on gs://<BUCKET> with Uniform Bucket-Level Access—never project-wide Storage Admin.

VM Org-Policy Friendly

Executes in Google-managed tenant projects; strict Compute Engine policies (vmExternalIpAccess, requireShieldedVm) never block serving.

OAuth/IAM + Optional PSC

Every inference call requires authenticated aiplatform.endpoints.predict tokens, with optional Private Service Connect (PSC) VPC isolation.

GPU Billing Safety Caps

Audit every mutation upfront with --emit-iam, auto-teardown base GPUs during tuning, and terminate endpoints via --auto-cleanup.

AUTOMATED 4-STAGE PIPELINE

From Hugging Face Hub to Fine-Tuned vLLM Endpoint

Run unattended via ./deploy/run_cloud_shell.sh --deploy --auto-cleanup or execute each Python module step-by-step.

01

Stage Open Weights & Validated JSONL to Cloud Storage

~3–5 min

Builds deterministic Cymbal incident triage JSONL splits (120 train, 12 val keeping validation byte ratio at 10.4% <= 25%, plus 8 evaluation prompts) and stages all 11 Qwen/Qwen3-4B .safetensors & tokenizer files (~8.06 GB) to regional Cloud Storage.

python3 src/generate_dataset.py && python3 src/stage_hf_weights.py --project="$PROJECT_ID" --bucket="$BUCKET_URI" --hf-repo="Qwen/Qwen3-4B" --cleanup-local
02

Deploy As-Is CustomModel on Managed vLLM & Benchmark Baseline

~9–15 min deploy · ~2–3 min eval

Auto-selects live GPU stock via list_deploy_options(available_machines=True, filter_by_user_quota=True), deploys Google's prebuilt pytorch-vllm-serve Dedicated Endpoint, and verifies the untuned baseline scores 0 / 8 (0.0%) exact match via OpenAI SDK + endpoint.predict().

python3 src/deploy_custom_weights.py --project="$PROJECT_ID" --gcs-uri="$BUCKET_URI/hf-weights/Qwen--Qwen3-4B" --endpoint-display-name="byom-base-ep" --model-display-name="byom-base-model" --machine-type="auto"
03

Tear Down Base Endpoint & Run Global Serverless Fine-Tuning

Wait ~40m–3.5h · ~$0.09 est.

Deletes the temporary base GPU endpoint to prevent idle replica charges, then submits FULL supervised fine-tuning (epochs=5, learning_rate=5e-5) with --location="global" (google-genai SDK) directly on your staged GCS weights—exporting standard .safetensors shards to postprocess/node-0/checkpoints/final.

python3 src/finetune_open_model.py --project="$PROJECT_ID" --location="global" --sdk="google_genai" --custom-base-model="$BUCKET_URI/hf-weights/Qwen--Qwen3-4B" --train-dataset="$BUCKET_URI/datasets/train.jsonl" --output-uri="$BUCKET_URI/tuning-runs/qwen3-4b-e5" --epochs=5 --learning-rate=5e-5
04

Deploy Exported .safetensors Checkpoint, Compare & Tear Down GPUs

~12–16 min

Deploys the newly exported fine-tuned .safetensors directory back onto a Managed Dedicated Endpoint, evaluates the identical 8-ticket benchmark, writes results/comparison_report.md, and tears down active GPU replicas via --auto-cleanup or --cleanup.

python3 src/compare_results.py --output-md="results/comparison_report.md" && ./deploy/run_cloud_shell.sh --cleanup
READY FOR GOOGLE CLOUD SHELL

Run the Complete BYOM Pipeline Today

Switch between automated Google Cloud Shell execution, non-mutating IAM inspection, manual SDK commands, or the 100% offline test suite.

cloudshell:~/AgentForge Automated 4-Stage Pipeline (--deploy --auto-cleanup)
CLOUD SHELL · BASH
git clone https://github.com/mbettan/AgentForge.git
cd AgentForge

export PROJECT_ID="<YOUR_PROJECT_ID>"
export REGION="us-central1"

# 1. Inspect least-privilege bucket IAM & APIs (read-only dry-run)
./deploy/run_cloud_shell.sh --emit-iam

# 2. Verify active gcloud auth, project access & APIs
./deploy/run_cloud_shell.sh --preflight

# 3. Execute all 4 stages unattended (~1-3.5h) & delete GPU endpoints when finished
./deploy/run_cloud_shell.sh --deploy --auto-cleanup